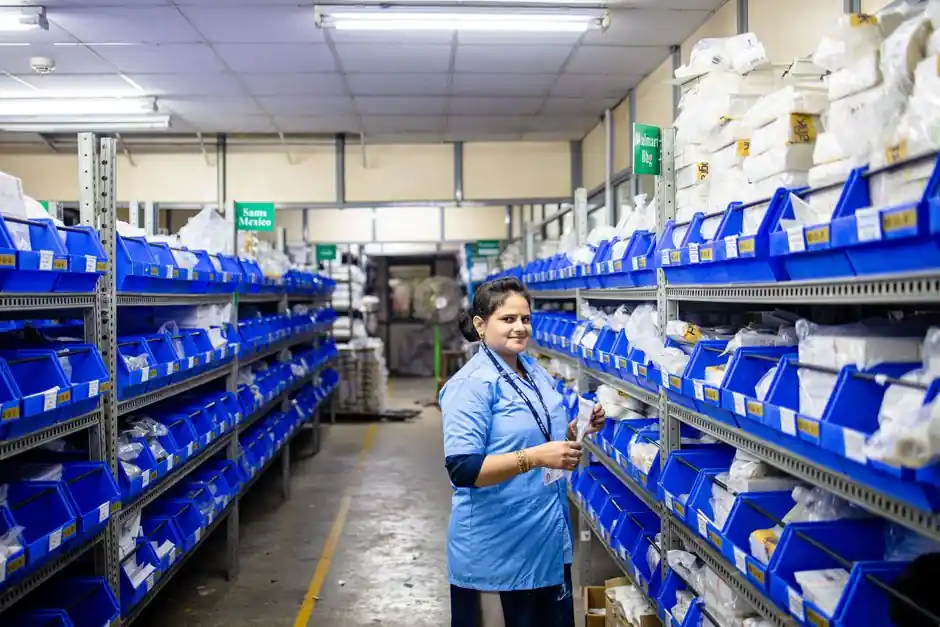
Plants should replace blanket spare-parts targets with three inputs: production consequence, replacement lead time, and the availability of qualified substitutes.
A single missing proximity sensor can shut down an entire production line.
Critical Spares Need Risk-Based Classification
Three-tier classification separates items that stop production from items that merely degrade performance.
This classification must combine asset criticality with part replaceability. The first dimension measures the effect of failure on production, safety, and financial performance, while the second covers lead time, number of qualified suppliers, approved substitutes, and failure frequency [S3].
VED analysis supplies a useful starting point: Vital items stop production and have no workaround, while Essential items cause significant slowdown or partial line impact but allow production to continue in a degraded mode. Criticality-based classification considers production impact, lead time exposure, and failure consequence before applying a stocking policy that matches the risk.
The practical result is four quadrants: high-consequence and hard-to-replace parts need the strongest protection; high-consequence and readily replaceable parts need controlled replenishment rather than large buffers; lower-consequence items require proportionate coverage, with scarce low-impact parts handled according to availability and cost [S3].
Lead Time and Substitutability Set the Stocking Policy
A low-cost part with a 12-week procurement lead time and no substitute can outrank an expensive item available from regional suppliers within one day, because the relevant risk is downtime exposure rather than purchase price [S4].
The comparison is straightforward:
A flat 95% service level is a poor default because it overprotects cheap consumables while allowing stop-critical spares to run thin [S3]. Stocking policies should reflect criticality and the risk of production interruption rather than applying the same service level to every part.
Build the List From Four Data Sets
Bill-of-materials analysis is the starting point, not the finished inventory policy. It identifies long-lead, single-source, and predictably wearing components, while failure history adjusts quantities for parts that fail repeatedly in comparable service [S1].
Operational context then tests the list against actual exposure. A three-shift plant with weekend overtime has a different recovery exposure from a single-shift operation, so production impact and restoration time must influence both quantity and location [S1].
Replenishment Must Be Visible, Controlled, and Auditable
Every issue of a critical spare should reduce recorded on-hand stock and trigger the reorder rule. Unlinked consumption, handwritten records, missing criticality flags, and absent min/max or kanban triggers allow tagged critical stock to disappear without replenishment [S2].
Operational controls should include controlled removal and a CMMS transaction for every issue. For electrical automation spares, the same discipline should cover the physical item, firmware version, configuration data, and approved substitute status, because a shelf label alone does not establish that a replacement will restore operation.
Central Stocking Fits Some Plants, Not Others
A plant with several lines should compare local stock, shared regional inventory, and central inventory before assigning quantities to each bin. Independent plant responses to past stockouts can produce duplicated buffers across a network, increasing carrying cost while leaving specific coverage gaps unresolved [S3].
Central pooling is suitable for common components used across multiple assets because one network stock position can cover several sites. Local stock is more defensible for custom, long-lead, non-substitutable automation parts used by a single line or remote site. Remote power installations illustrate the distance effect: a replacement that takes 11 weeks to reach a site requires protection even when the component itself costs only a few thousand dollars [S5].
Used automation equipment should not be mixed into critical buffer stock without compatibility checks, and OEM exit planning raises a separate risk that requires the OEM’s exact configuration, firmware, and spare-part data. The OEM exit spares issue is relevant because a nominally equivalent replacement may not preserve control-system behavior, certification, or interchangeability.
Ownership and Verification Prevent Recurrence
Critical-spare governance should assign responsibility to reliability, maintenance, purchasing, and stores personnel rather than treating the inventory list as a purchasing document alone. Monthly spot checks, low-level alerts, visible labels, controlled withdrawals, and automatic reorder triggers address the documented causes of silent depletion [S2].
Consumption data should also trigger root-cause review. Repeated use of the same critical sensor or module can indicate vibration, washdown exposure, connector failure, an overworked asset, or a design defect rather than a normal replacement cycle [S1][S2].
Management can track four measurable outputs: the number of critical parts with no named owner, the percentage of issues posted to the CMMS, stockouts avoided through automated alerts, and the measured restoration time after a critical failure. The buyer buffer-stock method becomes more defensible when each quantity can be traced to consequence, lead time, supplier availability, and observed failure data.
The next control point is the next monthly storeroom review: compare each Tier 1 automation spare against its approved quantity, current on-hand balance, lead time, substitute status, and last physical verification.