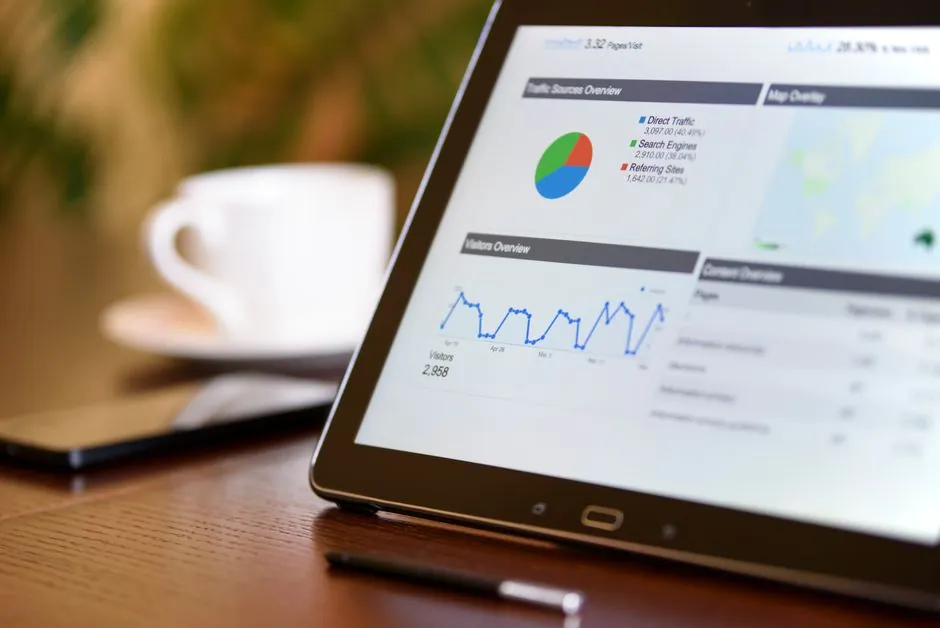
Leak-test analytics should monitor statistical distribution changes in pressure, flow, and background-dampening signals so small leaks are detected before routine pass or fail testing identifies them.
Data drift monitoring can help detect systematic changes in input distributions and can be useful for identifying deterioration in deployed model performance.
What Leak-Test Drift Detection Measures
Data drift is the systematic change in the distribution of input features, and it can degrade a model's performance even when the model continues to produce valid outputs [S1]. In leak testing, the equivalent condition is a sustained change in the test population relative to the reference population, such as a gradual increase in pressure-decay rate across otherwise comparable assemblies.
Covariate drift concerns changes in input-feature distributions, concept drift concerns changes in relationships between inputs and outputs, and prediction drift concerns changes in model outputs relative to expected patterns. A robust architecture therefore does not treat a rising rejection rate as the only drift indicator. It compares like-for-like test regimes and retains enough metadata to explain why two pressure-decay curves differ.
Choosing the Right Leak-Test Signals
If those variables change, the reference population must be segmented or the drift alarm may represent a different test condition rather than a worsening leak process.
Data acquisition should also include the raw signal, not just the pass or fail result. The raw trace supports later recalculation, curve-shape analysis, sensor-plausibility checks, and comparison with instrument specifications.
PSI, Thresholds, and Statistical Monitors
The thresholds are screening rules, not physical leak limits. A PSI alarm should identify the distribution that changed, while the pressure-decay rate and allowable leak threshold determine whether the process crossed a specified acceptance criterion. Keeping these layers separate prevents a population shift caused by a new product mix from being mislabeled as a leak-rate deterioration.
Sequential analysis methods, model-based methods, and time-distribution methods are the three main families identified for detecting drift [S2]. Data drift can be identified using sequential analysis, model-based, and time-distribution-based methods. Model-based methods are one of three families of methods identified for detecting data drift. Time-distribution methods compare feature distributions across periods, making them practical for batch and campaign comparisons.
Comparing the Main Detection Methods
PSI, sequential analysis, model residuals, and simple threshold exceedance answer different questions: Does the population look different, is change accumulating, does the curve violate its expected physics, and did one test fail? A sound leak-test monitor can use all 4, but it must keep the decision roles separate. [S5]
For comparison, PSI measures population movement, sequential analysis measures accumulated change, and residual monitoring measures physical deviation.
Who Benefits from Early Leak Analytics
Early drift analytics is for production lines, leak-test laboratories, validation groups, and maintenance teams that repeat a standardized test across many units.
It is not a substitute for calibration, leak-rate calculation, or acceptance testing. It is also poorly suited to one-off tests with no stable reference population, because drift requires a defensible comparison baseline. Teams should not deploy a generic alert across dissimilar products, fixtures, gases, pressure levels, or dwell times without segmentation.
Sample size and population features materially affect the outcome of drift detection. Empirical work on real-world medical imaging found that monitoring performance alone was not a good proxy for detecting input drift, and that drift-detection effectiveness depended heavily on sample size and patient features [S1]. The engineering lesson transfers directly: a leak-test alarm cannot be judged solely by the number of failed units, because a stable failure rate can coexist with a deteriorating distribution.
Deployment Architecture and Control Loop
The minimum deployment should include 4 layers: acquisition, feature calculation, baseline comparison, and controlled review. Acquisition captures the pressure or flow trace, timestamp, temperature, test recipe, instrument identity, and result. Feature calculation produces leak rate, decay slope, curve residual, threshold margin, and cycle time. Comparison evaluates those features against a frozen reference period. Review converts alarms into a hold, investigation, fixture check, calibration check, or recipe review. [S4]
Alarm logic should state the minimum evidence, the affected population, and the required response. For example, an alert should identify whether the PSI increase came from pressure slope, temperature, test duration, or a particular product family, rather than sending only a single scalar. Production systems described for drift monitoring combine alerts, policy thresholds, version tracking, and automated evidence capture [S5].
The historical retention decision affects this loop. How much historical data makes analytics pay off? is relevant when choosing the reference window, because the baseline must include enough representative cycles to characterize normal variation without freezing obsolete conditions.
Limitations, Failure Modes, and Evidence
Drift monitoring has 5 common failure modes: an unrepresentative baseline, changing test recipes, mixed product populations, sensor degradation, and threshold alerts that do not identify the shifted feature. Each can produce an apparent process change without an actual change in leak performance. Segmentation by product, fixture, gas, pressure, temperature, and date reduces false attribution. [S1]
Instrumentation faults must also be separated from process faults. Pressure or flow channels can drift because of sensor age, tubing restrictions, fixture wear, valve leakage, or calibration error. A rise in measured decay rate should therefore be checked against reference-leak standards, control units, and instrument status before it is assigned to the tested assembly.
Documentation should preserve the exact drift definition, binning rule, reference interval, sample count, metric version, alert threshold, analyst decision, and corrective action. This is more useful than a dashboard headline because it lets auditors reconstruct whether the system detected a real distribution change and whether the response followed the engineering rule.
Operational monitoring can detect changes within hours, whereas teams relying on user complaints or quarterly reviews may find degradation only after weeks or months [S5]. For leak testing, the corresponding trackable signals are the first sustained PSI increase, the first negative shift in pressure-decay margin across matched recipes, and confirmation from calibration or control-unit results.